Nucleation
Nucleation forms candidate events from picks. Catalyst offers five methods, each on its own tab in the Pick processing → Nucleation panel. All of them
work on the picks shown in the pick list, or only on the selected picks if picks are selected,
ignore picks that are hidden by the pick filters,
create one preliminary seed origin per detected event,
use only the settings of their own page. The Phase setting and Min size of DBSCAN apply to DBSCAN alone: back projection uses the phases ticked on its page, GaMMA-lite P and S, the grid search and EDT location P.
Picks that already belong to an origin take part as well when they are shown. To nucleate only the remaining picks, untick Show associated in the pick filters (see Pick filters); the status line reports how many of the nucleated picks were already in an origin.
A seed origin is only a starting point. Locate the seeds afterwards, usually with Smart-locate all (see Analyst rules and Smart-locate), and remove duplicates with Merge origins (see Refining origins).
The number of origins nucleation may create is limited by
nucleator.maxOrigins in catalyst.cfg.
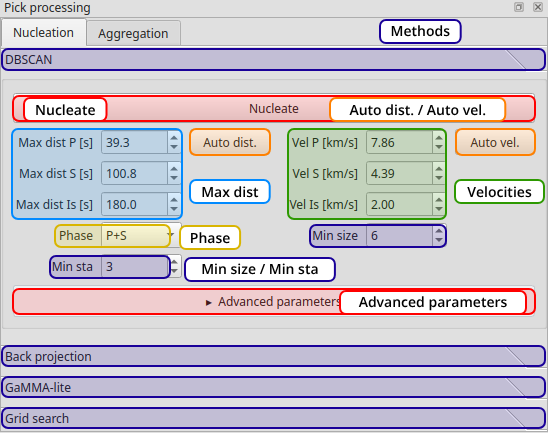
The Nucleation panel with the DBSCAN page open. Each method is a page of the panel; Nucleate runs the open one. The DBSCAN parameters are described below.
DBSCAN
DBSCAN [1] groups picks that are close to each other in time and space. The distance between two picks is measured in seconds as the vector sum of
their pick-time difference and
the distance between their stations divided by a velocity.
A pick with at least Min size picks, itself included, within Max dist starts a cluster. Clusters grow through neighbouring picks. Each cluster that spans at least Min sta different stations becomes a seed origin.
The picks are played back in time order. At each pick only the picks not older
than Window take part in the search, like maxPickDelay in
scanloc. The window must be at least as long as the pick-time span
of one event.
Parameter |
Description |
|---|---|
Phase |
Picks to cluster: |
Max dist P / S / Is [s] |
Largest distance between two neighbouring picks (DBSCAN eps), per phase. |
Vel P / S / Is [km/s] |
Velocity that converts station distance into time. Roughly 6–7 for P, 3.5–4 for S and 0.34 for infrasound. |
Min size |
Minimum number of picks in a cluster. |
Min sta |
Minimum number of different stations in a cluster. A cluster from only one or two stations cannot be located, however many picks it has. 0 switches the check off. |
Window [s] |
Part of the pick buffer used for the search. 0 = 180 s. |
Use 3D distances |
Include the station elevation in the station distance. |
Dist pctl [%] |
Percentile used by Auto dist. 100 = maximum. |
Pg max [km] |
Only picks within this distance are used for the apparent-velocity fit, so that one line is not fitted across the Pg/Pn crossover. 0 = all picks. |
Choosing the parameters from trusted events
Select a few well-located origins in the origin table first, then use the buttons next to the fields:
Auto vel. to set the velocity to the median apparent velocity of the selected origins, fitted from their used picks of the chosen phase,
Auto dist. to set Max dist with the k-distance method: the chosen percentile of each member pick’s distance to its (Min size − 1)-th nearest neighbour,
Auto next to Window to set the window from the largest pick-time span of the selected origins, with a margin.
Fit V on the Move-out tab of the active origin sets the velocity from a single origin.
Back projection
Back projection searches a grid of trial sources. For each grid node it computes the origin time implied by each pick and counts how many picks agree on a common origin time within t0 tol. Nodes with enough agreeing picks become detections.
Several phases can be used together (joint search): a pick then supports a node if any of the selected phases explains it. Picks that carry a measured back-azimuth, for example from arrays, only support nodes within Az tol of their bearing.
For station sets wider than about 400 km the search uses spherical geometry.
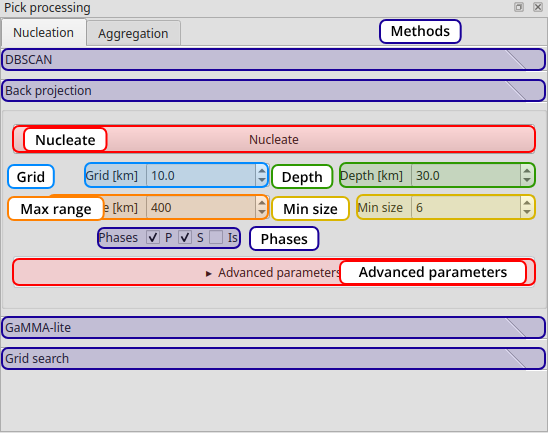
The Back projection page.
Parameter |
Description |
|---|---|
Grid [km] |
Spacing of the search grid. Finer is slower. The seed only needs to be good enough for the locator to converge. |
Depth [km] |
Depth assumed during the search. 0 suits infrasound and shallow events. |
Max range [km] |
Largest source–station distance, and the margin the grid adds around the stations. |
Min size |
Minimum number of picks for a detection. |
Phases |
P, S and Is. Tick several for a joint search. |
t0 tol [s] |
How closely picks must agree on the origin time. |
Az tol [deg] |
Back-azimuth tolerance for picks that carry one. |
Max az gap [deg] |
Reject detections with a larger station azimuthal gap. 360 = off. |
EDT stacking |
Score each node with an EDT stack instead of counting picks (see below). |
EDT σ [s] |
Differential-time uncertainty for EDT stacking. |
EDT stacking
With EDT stacking each node is scored by an Equal Differential Time stack [2]. Every pick pair adds a Gaussian of its differential-time residual. The differential time does not depend on the origin time, so the stack is robust against a wrong seed time, and a bad pick, which disagrees with all its pairs, cannot build up score. It is slower than counting, but often cleaner in swarms.
EDT σ controls the width of the Gaussian. Too small finds only near-perfect events; too large merges nearby sources. Auto σ estimates it from the origins currently shown in the origin table: the robust (MAD) spread of their travel-time residuals, scaled by √2 for a pick pair. Filter the origin table to trusted origins first.
For infrasound the travel times scatter by tens of seconds: the celerity varies between about 0.26 and 0.34 km/s with the propagation path. The infra profile therefore uses EDT stacking with EDT σ 10 s, t0 tol 30 s, Az tol 8°, a 10 km grid and 800 km range. EDT σ goes up to 60 s.
Each origin uses at most one pick per station and phase. A second pick of the same station and phase within 5 s of the best one is attached with weight 0; picks further away are left unassociated. Rapid sequences such as missile salvos, where several sources fire within a minute, thus keep their extra picks for Template match (see Swarm tab: recovering further events).
GaMMA-lite
GaMMA-lite is a simplified implementation of the GaMMA phase association method [6]. Picks are first grouped by time with a coarse window. Within each group, an epicentre grid search and the origin-time spread separate the events.
Parameter |
Description |
|---|---|
Grid [km] |
Epicentre search grid spacing. |
Coarse window [s] |
Time window for the coarse grouping of picks. |
OT tol [s] |
Origin-time gap that separates two events within a group. |
Processing window [s] |
Sliding window for large data sets. 0 = one pass over all picks. Must exceed the pick-time span of the longest event; 90–120 s for a local network. |
Min size |
Minimum number of picks for an event. |
Depth [km] |
Initial source depth. |
Max range [km] |
Largest source–station distance. |
Max OT spread [s] |
Reject a cluster whose best origin-time spread is larger. |
Grid search (scautoloc approach)
The grid-search nucleator follows the approach of scautoloc and reads a grid file in the same format. Like scautoloc, it nucleates on P picks. For each node of the grid it projects the picks back to the node and looks for enough stations that agree on an origin time.
Parameter |
Description |
|---|---|
Grid file |
Path to a |
Station file |
Optional |
Min. stations |
Lowest number of stations that must agree at a node. A node’s own minimum applies if it is higher. |
Max. distance [deg] |
Largest station distance. |
Agreement offset [s] |
Additive term of the arrival-time agreement window. |
Projected window [s] |
Rough projected-time window per node; scautoloc uses 50 s. |
Max. radius factor |
Reserved. Set to 0 to ignore it. |
Processing window [s] |
Trim each node’s pick buffer to this span. 0 = no trimming, the safe setting. |
The usage flag of the station file is honoured: a station with usage 0 does not take part.
EDT location
EDT location follows the method of RTLoc [4], written for
Catalyst from the publication (plugin nucleator_edtloc). Each P pick
starts a candidate with the P picks of other stations that follow within the
window. The candidate is located with the equal differential time (EDT)
likelihood: for every pair of picks, the observed time difference is
compared with the predicted one, so the origin time drops out and a single
wrong pick only spoils its own pairs. An octree search refines the most
likely cells of a box around the first station. Picks with a large residual
are removed and the candidate is located again; an accepted origin also takes
the later P picks that fit it.
Stations that have not picked. A station counts as working if it has any loaded pick within an hour of the candidate, and as silent if it has no pick from the first pick of the candidate until its Min. picks-th pick. Sources from which the P wave would already have reached a silent station become less likely, by the factor Miss prob. per station. Sources the wave has not reached yet cost nothing. This is what keeps chance coincidences of noise picks out: on New Madrid picks with two noise picks per station and hour, EDT alone accepted 472 false seeds in 12 days and lost 18 % of the events, while with the silent stations 12 false seeds remained and 97 % of the events were found (median epicentre error 0.9 km against ComCat).
A working station without a pick is not always one the wave has not reached: noisy stations miss small events, and analysts do not pick every station. Miss prob. keeps the term soft, and the silence of some stations can be ignored:
over-detecting stations (
qc.overdetection.stations, or more thanqc.overdetection.factortimes the median number of picks),the stations in Exempt stations (
NET.STA,NET.*,*.STA),a scautoloc
station.confas Station file: usage 0 leaves a station out completely, and a station’s pick and its silence only count for sources within its maximum nucleation distance.
Parameter |
Description |
|---|---|
Window [s] |
P picks within this time after a first pick form a candidate. It must cover the P moveout across the stations of an event. |
Min. picks |
P picks of different stations a candidate and an origin need. It is also the pick whose time is now for the silent stations. |
Pick sigma [s] |
Error of one P pick including the travel-time model. |
Miss prob. |
Probability that a working station misses the P pick of an event. Smaller values trust silent stations more. |
Search radius [km] |
Half width of the search box around the station of the first pick. Maxima at the box edge are rejected. |
Max. depth [km] |
Deepest source the search tries. |
Max. residual [s] |
Picks with a larger residual are removed; later P picks within it join the origin. |
Max. RMS [s] |
Origins with a larger RMS are rejected. |
Use stations that have not picked |
The silent-station term. Off, the method is a plain EDT locator. |
The travel times come from the model selected in the locator panel; the
locator tables need to be accurate at local distances (iasp91_scanloc
rather than iasp91). Further parameters (octree budget, smallest cell,
the now pick, the activity window) can be set in catalyst.cfg as
nucleator.edtloc.*, see apps/nucleator_edtloc/PARAMETERS.md.
Choosing a method
DBSCAN is fast and needs no velocity model beyond one velocity per phase. It works best for local networks and for picks from a compact source region, such as swarms.
Back projection handles sparse and irregular networks, infrasound and array picks with back-azimuths, and large regions.
GaMMA-lite separates events that overlap in time.
Grid search follows the nucleation approach of scautoloc and reuses its grid configuration.
EDT location gives the most accurate seeds on a dense local network and rejects noise coincidences through the stations that have not picked. It needs P picks and a travel-time table that is accurate at local distances.